Indian AI Startups Target the “Model Routing” Opportunity: Slashing Enterprise Inference Costs and Latency
By Elena Rostova | Published September 22, 2026 | 9 min read
Indian AI infrastructure startups are building intelligent model routing layers, dynamically orchestrating LLM queries across cost, latency, accuracy, security, and data governance.
A fast-emerging cohort of Indian artificial intelligence infrastructure startups is building dynamic 'model routing' layers—intelligent software gateways that automatically evaluate enterprise prompts and route them to the most efficient AI model. By balancing token costs, response latency, accuracy, and regulatory governance in real time, these startups are solving one of the most acute challenges confronting enterprise AI adoption: runaway cloud inference bills.
Over the past two years, global enterprises rushed to deploy generative AI applications by plugging directly into proprietary frontier Large Language Models (LLMs) such as OpenAI's GPT-4o, Anthropic's Claude 3.5 Sonnet, and Google's Gemini Pro. However, as pilot projects transitioned into high-concurrency production deployments handling millions of daily queries, companies discovered that relying on monolithic frontier models for routine tasks is commercially unsustainable.
Indian AI founders—drawing on the nation's deep systems engineering heritage—are seizing this friction point as a high-margin global infrastructure opportunity.
The Economic Crisis of Monolithic LLM Inference
In enterprise production environments, an estimated 65% to 75% of incoming AI queries consist of relatively straightforward operational tasks: data extraction from invoices, text summarization, sentiment categorization, intent recognition, and deterministic JSON schema formatting.
Dispatching these routine requests to premier frontier models costing $5 to $15 per million tokens results in massive computational and financial waste. A fine-tuned Small Language Model (SLM) with 7 billion to 14 billion parameters running on cost-effective domestic GPU instances can execute identical tasks with equivalent accuracy, one-tenth the latency, and up to 90% lower operational expenditure.
However, enterprises cannot simply abandon frontier models, because the remaining 25% of queries involve nuanced multi-step reasoning, intricate legal interpretation, complex code synthesis, or ambiguous user intents that require maximum cognitive capability.
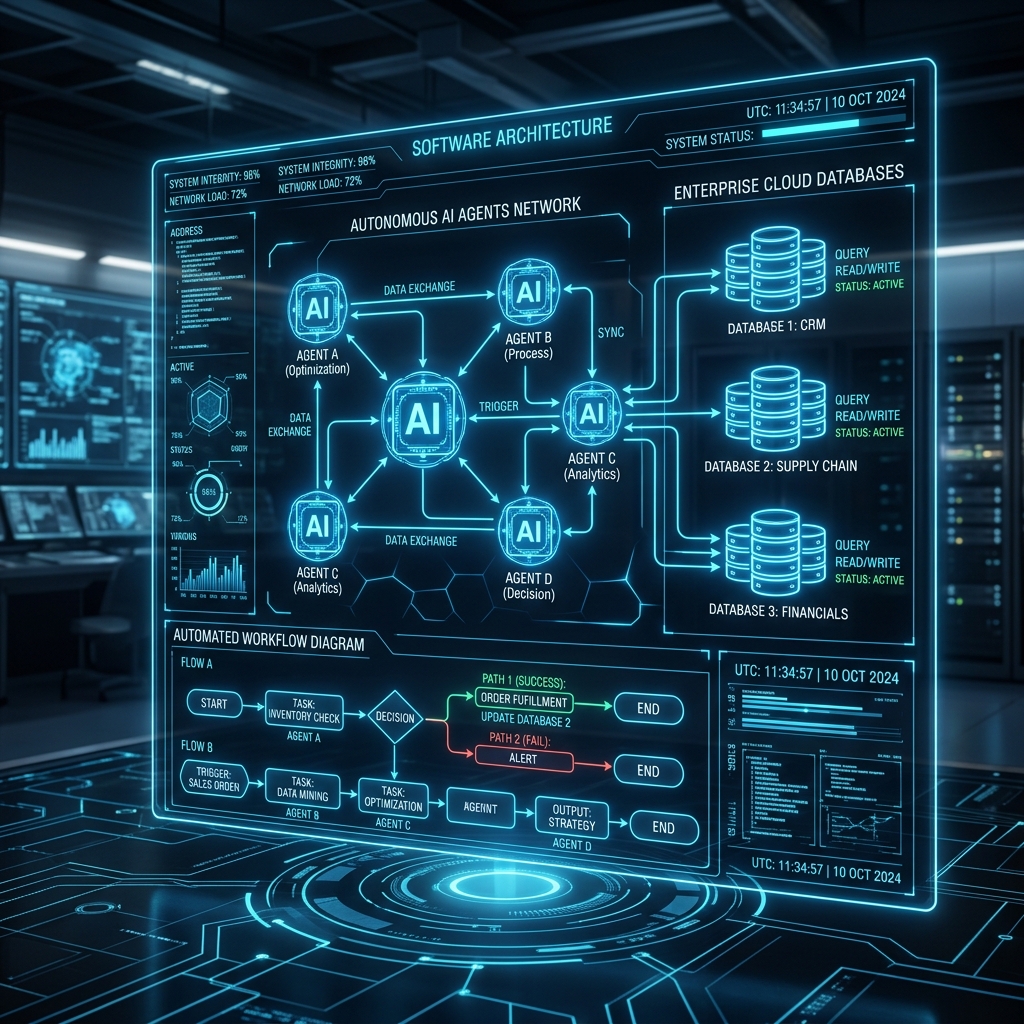
Model routing startups solve this dilemma by eliminating the need for developers to hard-code model choices into their application code. Instead, application queries pass through a single, intelligent routing proxy.
"Treating every incoming prompt with a frontier multi-billion-parameter model is the technological equivalent of dispatching a fleet of Boeing 747s to deliver daily neighborhood groceries,"observed leading enterprise AI architects. "Intelligent semantic routing brings common-sense unit economics to generative AI, ensuring you only pay for frontier cognitive horsepower when the problem genuinely demands it."
Anatomy of an Intelligent Semantic Routing Gateway
The core innovation of Indian model routing startups lies in building sub-10-millisecond decision engines that parse and dispatch prompts without introducing perceivable user latency.
A state-of-the-art model router executes a four-stage real-time evaluation pipeline:
- 1. Semantic Intent & Complexity Scoring: An ultra-lightweight classifier analyzes the semantic density, syntactic complexity, domain vocabulary, and prompt length, assigning a cognitive complexity score from 0.0 to 1.0.
- 2. Governance & PII Filter: The gateway identifies sensitive Personally Identifiable Information (PII), such as Aadhaar numbers, PAN identifiers, credit card data, or patient health records, immediately applying client-configured data residency policies.
- 3. Real-Time SLA Arbitration: The router cross-references the enterprise application’s Service Level Agreement (SLA)—such as a strict 200ms latency ceiling for customer support chatbots—against live model provider latency metrics.
- 4. Dynamic Model Dispatch: The query is routed to the optimal target: an open-source SLM (e.g., Llama 3, Mistral), a specialized Indic model (e.g., Sarvam, Gnani), or a proprietary frontier engine.
Quantitative Comparison: Direct Frontier vs. Intelligently Routed Architecture
The benchmark table below illustrates real-world enterprise performance gains achieved across standard high-volume workloads:
| Workload Domain | Direct Frontier Model Execution | Intelligently Routed Deployment | Latency Improvement | Cost Reduction |
|---|---|---|---|---|
| Customer Support FAQ | GPT-4o / Claude Sonnet | Localized Llama 3 8B SLM | 62% faster (180ms vs 470ms) | 88% cheaper |
| Document Classification | Gemini Pro API | DistilBERT / Qwen 2.5 Fine-Tune | 74% faster (95ms vs 360ms) | 92% cheaper |
| Code Generation & Review | Claude 3.5 Sonnet | Dual-tier: DeepSeek / Sonnet Escalate | 35% faster (avg across queries) | 48% cheaper |
| Financial Advisory & Risk | GPT-4o Direct | Hybrid: Local Indic SLM + Frontier Verifier | 40% faster on routine queries | 56% cheaper |
| Blended Enterprise Workload | Monolithic Single LLM | Intelligent 4-Tier Semantic Router | 52% average speedup | 68% blended savings |
Data Sovereignty and Domestic Regulatory Governance
For Indian enterprises in banking, financial services, insurance (BFSI), and healthcare, model routing is not merely a cost-saving tool; it is an existential compliance mechanism. Under Reserve Bank of India (RBI) guidelines and digital data protection mandates, sending customer banking queries or biometric data to cloud servers located outside India can trigger severe regulatory penalties.
Indian model routing startups have engineered sovereign compliance guardrails directly into their control planes. When a sensitive prompt arrives, the router can automatically mask PII in-flight, or enforce hard geographic constraints that route the token stream exclusively to on-soil datacenters.
This heightened focus on resilient, secure infrastructure complements broader enterprise security initiatives, aligning with lessons from frontier AI autonomous cybersecurity evaluations and mirroring the broader value migration powering India’s $221 billion software export economy.
Bridging Open-Source, Indic Models, and Global Frontier Systems
Another compelling advantage of domestic routing platforms is their native integration of Indic-language AI models. India’s multi-lingual population requires applications that comprehend Hindi, Tamil, Telugu, Marathi, and Hinglish with cultural and regional context.
Global foundation models frequently stumble on nuanced Indian linguistic phrasing or bill exorbitant token rates due to inefficient sub-word tokenization algorithms for Devanagari and Dravidian scripts. Indian routers solve this by routing vernacular queries to hyper-optimized domestic Indic models (such as those pioneered by Sarvam AI or AI4Bharat), while dynamically delegating code or complex analytical queries to global models.
As venture investors and enterprise CIOs prioritize sustainable unit economics and verifiable ROI, model routing is rapidly transitioning from an experimental optimization technique to a mandatory pillar of the modern enterprise software stack.
Frequently Asked Questions
What is AI model routing and why is it essential for enterprises?
AI model routing is an intelligent architectural layer positioned between enterprise applications and multiple underlying AI models. Instead of sending every request to expensive, high-latency frontier models like GPT-4o or Claude 3.5 Sonnet, a model router analyzes the intent, complexity, and security constraints of the prompt, directing simple queries to lightweight, low-cost models and reserving frontier models only for complex reasoning.
How do model routing layers achieve up to 68% cost reduction?
Studies show that between 60% and 75% of enterprise queries consist of routine extraction, classification, summarization, or structured JSON formatting. These tasks can be handled flawlessly by compact Small Language Models (SLMs) like Llama 3 8B or Mistral at 1/20th the cost. By only invoking high-end frontier models when required, overall token bills drop precipitously.
How do Indian routing startups address data governance and sovereign residency?
Indian routers feature on-premise and local cloud deployment options with integrated PII redaction and sovereign routing rules. Regulated organizations in banking, insurance, and healthcare can configure policies ensuring customer financial records and medical data are routed exclusively to localized, on-soil inference endpoints.
Can model routers switch models dynamically mid-conversation?
Yes. Advanced routers evaluate conversations turn-by-turn. If an ongoing interaction shifts from general chit-chat to complex mathematical reasoning, legal analysis, or multi-step code generation, the router dynamically escalates subsequent turns to specialized reasoning models while maintaining context memory.
Primary Sources & Official References
- Stanford AI Index & Enterprise LLM Inference Economics Working Paper: Quantitative empirical research on multi-model token economics and latency overheads.
- NASSCOM Enterprise Generative AI Architecture & Middleware Benchmark Study: Industry analysis of Indian enterprise AI budgets and software middleware adoption.
- Reserve Bank of India (RBI) & MeitY Guidelines on AI Cloud Data Residency and PII Governance: Official compliance directives on consumer financial data and cross-border inference.
- Association for Computing Machinery (ACM): Dynamic Neural Routing and Semantic Dispatch Algorithms: Academic foundations for low-latency prompt classification and semantic embedding arbitration.