AI Moves From Surface Feature to Core Foundation: How India's New Generation of Startups Build AI-Native Architectures
By Elena Rostova | Published September 29, 2026 | 8 min read
The software industry reaches a major turning point as Indian startups abandon cosmetic 'AI wrapper' features to construct deep AI-native software foundations.
The global technology ecosystem has crossed an irreversible architectural threshold, transitioning from the initial frenzy of superficial "AI wrappers" toward the rigorous construction of "AI-native" software foundations. Over the past two years, the enterprise landscape was saturated with products that merely added a conversational chat interface or a basic OpenAI API endpoint onto traditional database-backed CRUD (Create, Read, Update, Delete) applications. Today, institutional venture capital and discerning enterprise buyers are systematically discarding these cosmetic bolt-ons in favor of software built from the ground up on machine intelligence.
This structural evolution is reshaping the startup formation playbook across Bengaluru, Delhi-NCR, and Silicon Valley. Where first-generation AI ventures competed on prompt engineering and viral UI gimmicks, modern AI-native startups are engineering deep architectural moats centered around stateful multi-agent loops, hybrid model orchestration, persistent context graphs, and proprietary data flywheels.
The Post-Mortem on 'AI Wrappers': Why Thin Layers Collapsed
The rapid obsolescence of early generative AI startups offers a masterclass in technology defensibility. In 2023, hundreds of venture-backed companies emerged offering "ChatGPT for PDFs," "AI copywriters," or "automated customer service bots."
Within eighteen months, the vast majority encountered severe existential headwinds driven by three structural flaws:
1. Zero Defensibility Against Platform Encroachment: Because these tools were thin layers atop public API endpoints, foundation model providers like OpenAI, Google, and Anthropic wiped out entire market categories with single product updates (e.g. OpenAI introducing native PDF uploads and custom GPTs).
2. Brutal Unit Economics and Token Churn: Paying retail token prices for high-end frontier models to handle routine queries destroyed gross margins. Companies operating at 30% gross margins found it impossible to compete against traditional SaaS businesses operating at 80% margins.
3. Hallucination in High-Stakes Workflows: Enterprise customers refused to trust probabilistic chat interfaces for mission-critical operations like financial auditing, legal compliance, or healthcare billing without deterministic verification layers.
"If your entire company can be rendered obsolete by an OpenAI dev day announcement, you didn't build a software company; you built a transient feature,"observed venture analysts tracking early-stage software investments. "AI-native founders do not ask how to integrate AI into existing software; they ask what software looks like when machine intelligence is the foundational substrate."
The Architectural Blueprint: AI-Wrapper vs AI-Native
The table below delineates the profound structural differences between legacy wrapper approaches and modern AI-native foundations:
| Architectural Layer | Legacy 'AI Wrapper' Approach | Next-Generation 'AI-Native' Foundation |
|---|---|---|
| User Interface (UI) | Passive chat box / text input field | Dynamic generative canvas, headless agent triggers, intent-driven dashboards |
| Execution Engine | Single-turn synchronous API call | Multi-agent state machines, directed acyclic graphs (DAGs), deterministic validation |
| Model Strategy | 100% reliance on a single frontier closed API | Dynamic semantic routing: Frontier models (reasoning) + Fine-tuned SLMs (execution) |
| Memory & Context | Stateless / ephemeral session memory | Multi-tiered persistent context graph (vector, keyword, relational, and episodic memory) |
| Data Feedback Loop | Zero feedback; user data sent outward | Continuous operational telemetry captured locally to refine domain-specific models |
| Gross Margin Profile | 25% – 45% (Eaten by API inference fees) | 70% – 85% (Optimized via self-hosted quantized models and edge caching) |
The Four Pillars of the AI-Native Stack
Startups emerging from elite incubators like Peak XV's Surge cohort are constructing their software according to four technical pillars:
1. Multi-Agent State Machines and Deterministic Verifiers
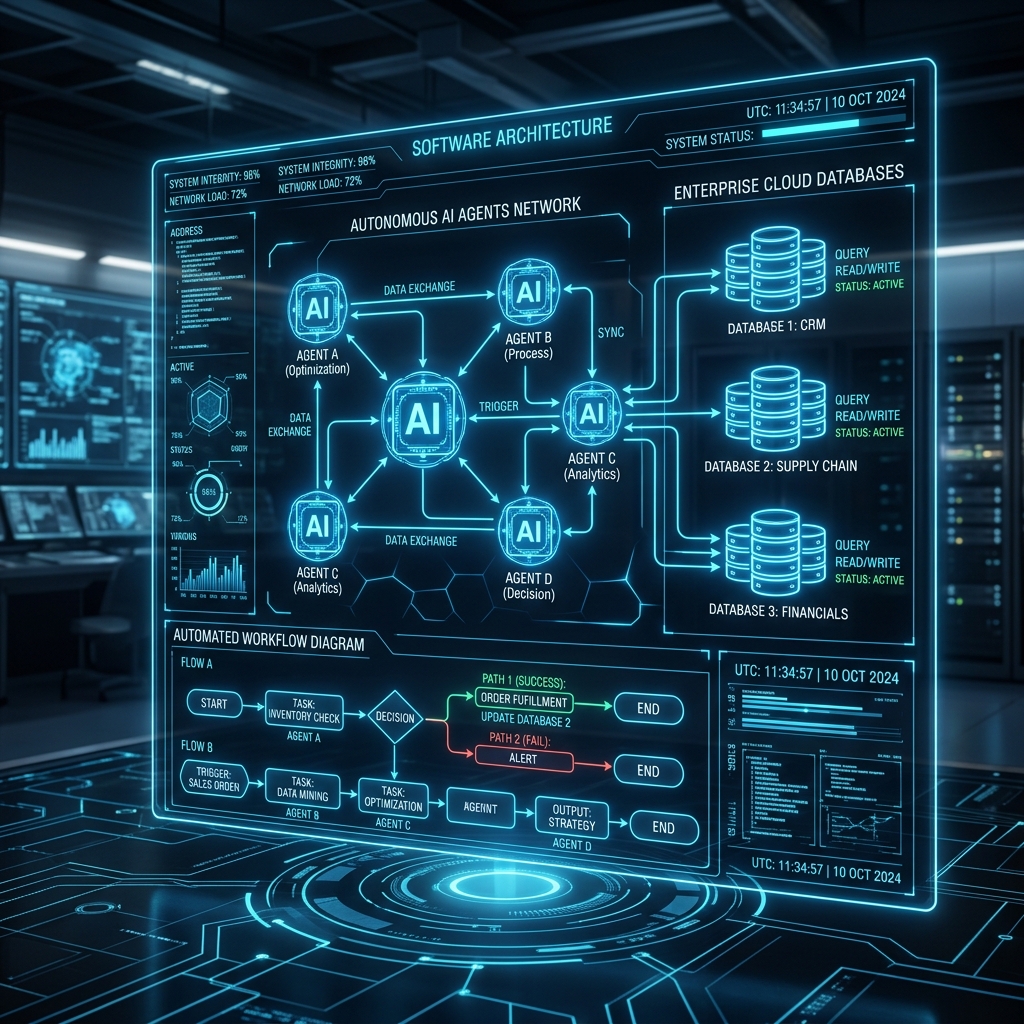
Instead of relying on a single monolithic LLM prompt to solve complex tasks, AI-native applications orchestrate swarms of specialized agents. An intake agent parses user intent, a retrieval agent gathers verified facts, an execution agent writes code or executes API calls, and a separate deterministic verification agent evaluates the output against formal logical constraints before presenting results to the user.
2. Intelligent Cost and Semantic Model Routing
AI-native architectures abandon the costly habit of sending every prompt to expensive frontier models like GPT-4o or Claude 3.5 Sonnet. Using lightweight classification routers, systems direct 70% of routine categorization, data extraction, and formatting tasks to quantized, self-hosted Small Language Models (SLMs) such as Llama 3 8B, Mistral, or domestic Indic models running on internal GPUs at pennies per million tokens. Frontier models are invoked exclusively when multi-step abstract reasoning is strictly required.
3. Persistent Knowledge and Context Graphs
Rather than cramming millions of raw tokens into expanding context windows, AI-native platforms maintain unified knowledge graphs. By linking dense vector embeddings with sparse BM25 indices and temporal relational databases, the software understands not just what a user said three minutes ago, but how that query connects to emails exchanged three months ago and internal corporate policy documents.
4. Compounding Data Flywheels
The ultimate defensibility of an AI-native venture is not the model weights—which commodity open-source releases frequently surpass—but the proprietary telemetry generated through live usage. Every human correction, approved pull request, and confirmed reconciliation step creates high-value reinforcement learning from human feedback (RLHF) and direct preference optimization (DPO) datasets that no competitor can scrape from the public internet.
To examine how the latest crop of 18 early-stage startups is putting this architectural philosophy into practice, see our coverage on /post/peak-xv-backs-18-new-startups-surge-cohort.
The Enterprise Transition in India
The architectural shift is having an immediate impact across India's domestic enterprise and banking sectors. Major institutions are abandoning experimental chatbots and procuring end-to-end autonomous underwriting and compliance pipelines that operate within their sovereign virtual private clouds.
As detailed in our analysis of Axis Bank's workforce restructuring in /post/axis-bank-plans-12500-campus-hires-ai-push, human professionals are no longer interacting with AI as novelty chat companions, but as algorithmic co-pilots executing structured industrial tasks.
The Long-Term Horizon
The transition from AI as a superficial feature to AI as an architectural foundation marks the end of the generative AI hype cycle and the commencement of the industrial utility cycle. Founders who master semantic routing, multi-agent verification, and proprietary context indexing will build the enduring software enterprises of the next generation.
Frequently Asked Questions
What is the difference between an 'AI-enabled' product and an 'AI-native' product?
An 'AI-enabled' product is a legacy software application (like a traditional CRM or ERP) that bolts on a third-party generative AI feature or chatbot. An 'AI-native' product is architected from inception around machine intelligence, where autonomous agents, vector indices, and probabilistic models drive the core user experience and business logic.
Why did many first-wave 'AI wrapper' startups fail?
First-wave AI wrappers had negligible technological defensibility. Because they simply forwarded user prompts to public models like GPT-4 via standard APIs, foundation model providers quickly replicated their features natively. Furthermore, they lacked proprietary data moats and suffered from unsustainable inference token costs.
What architectural components define an AI-native startup?
AI-native architectures typically feature four pillars: (1) stateful multi-agent execution engines, (2) persistent context memory graphs, (3) hybrid model routing between frontier LLMs and localized small language models (SLMs), and (4) continuous automated data flywheels that turn user interactions into training telemetry.
How do AI-native companies control inference compute costs?
Instead of sending every user request to expensive frontier models, AI-native platforms use intelligent semantic routers. Simple classification, data formatting, and routing tasks are handled by lightweight, quantized open-source models (like Llama 3 8B or Mistral) running at fractions of a cent, reserving frontier models only for complex reasoning.
Primary Sources & Official References
- Stanford Institute for Human-Centered Artificial Intelligence (HAI): AI Index Report & System Architecture Trends
- Sequoia Capital & Peak XV Research: Generative AI's Act Two – From Novelty Wrappers to Enduring Architectures
- ACM SIGMOD Record: Database Engines & Vector Graph Federation in Modern Agentic Applications
- NASSCOM Technology Council: The Evolution of India's SaaS Industry Toward AI-Native Workflows